Profiling#
Nupp includes a sampling profiler and a LuaJIT trace-abort report. Use them to find slow code and investigate why it stays interpreted:
nupp run --profile app.nupp       # where the time went
nupp run --jit-aborts app.nupp    # whether it ran compiled
LuaJIT can leave a loop interpreted when it cannot compile an operation inside it. The program still works, but may run much slower. Sampling shows where it spends time; the trace-abort report helps explain failed compilation.
For benchmarks, see Profiling a benchmark.
Both are available through nupp.profile. Sampling and trace sessions implement profile.Session. Its associated Report type lets a shared helper return the appropriate report type:
local profile = nupp.profile

local function finish<S is profile.Session>(borrows session: S): S.Report
    return session:stop()
end

with sampling = profile.sample() do
    local samples: profile.SampleReport = finish(sampling)
    print(samples.samples)
end
with tracing = profile.trace() do
    local aborts: profile.TraceReport = finish(tracing)
    print(aborts.totalAborts)
end
See Associated types for details on S.Report.
Sampling a program#
nupp run --profile app.nuppA timer periodically records the call stack. When the program finishes, Nupp writes the samples to profile.out and prints a summary:
nupp: 2043 samples on 61 stacks every 10ms, written to profile.outDrop profile.out on speedscope.app to view a flame graph. --profile-interval-ms 2 samples every 2 ms instead of the default 10 ms. Shorter intervals increase profiling overhead; use them for short captures. --profile-out changes the output path.
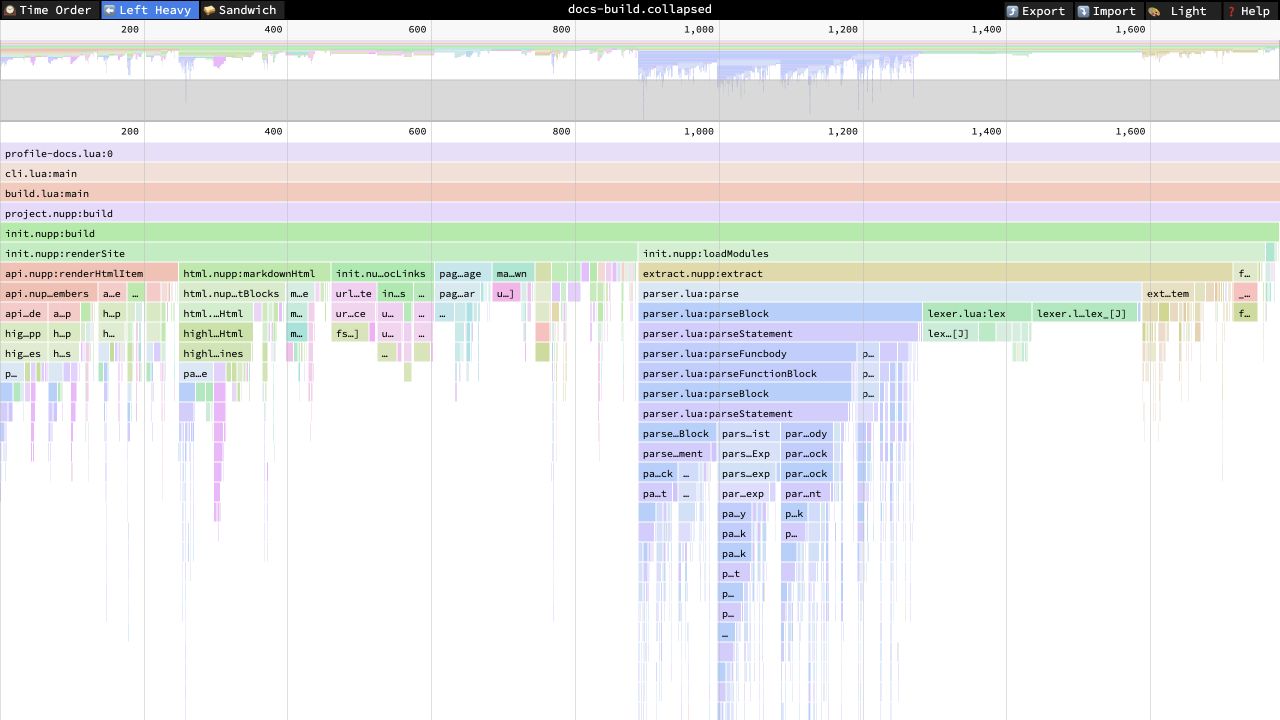
A documentation build captured with nupp.profile.sample, shown in speedscope's Left Heavy view. Wider blocks account for more samples. Click the screenshot to enlarge it.
Stack lines#
Each line is one stack: frames separated by semicolons, then the sample count.
frame;physics;app.nupp:0;app.nupp:step_[N] 431Each stack has a separate row for every observed VM state, with that state's actual sample count. The final frame identifies the state:
_[N]: running compiled machine code._[I]: in the interpreter._[C]: inside a C function._[G]: in the garbage collector._[J]: inside the JIT compiler.
C, GC, and JIT work has an explicit <C>, <GC>, or <JIT> leaf, so native work is not charged to a Lua callback. LuaJIT captures the state at the timer interrupt and inspects the stack later; native states therefore retain their zone but make no claim about which Lua frame called them.
If a hot function shows _[I], it is running in the interpreter. Use --jit-aborts to check for failed compilation attempts.
Omitted frames#
The report omits the loader and pcall frames belonging to nupp run, so stacks start at your program.
LuaJIT can inline several function calls into one trace. Those inlined calls have no separate stack frames, so the profile may show fewer calls than the source.
SampleReport.sourceSamples retains Lua leaf source-line counts with full paths. Native VM states are excluded from those counts. Combine run --profile with --remarks-out to join these observations to optimizer decisions in build/remarks.json.
Zones#
Zones label phases such as loading, physics, and rendering. They let you distinguish calls to the same function from different phases of your program.
nupp.profile.zone is a stack of names that the profiler reads:
local zone = nupp.profile.zone

local function frame()
    zone.push("frame")

    zone.push("physics")
    stepWorld()
    zone.pop()

    zone.push("render")
    drawWorld()
    zone.pop()

    zone.pop()
end
Each sample starts with the active zone path, grouping the flame graph by phase:
frame;physics;app.nupp:stepWorld_[N] 812
frame;render;app.nupp:drawWorld_[N] 233
Avoiding allocations while profiling
zone.path caches the joined path until the zone stack changes. Repeated reads reuse the string, avoiding allocations and extra garbage collection caused by the sampling callback itself.
Push and pop are intrinsics#
When no profiler is active, push and pop check a boolean and return. During profiling, calls inside a hot loop can interfere with trace compilation.
Nupp inlines push and pop when called as statements through a local binding such as local zone = nupp.profile.zone. This removes the function call; pop is only inlined when its return value is unused.
| Written as | Lowered | Reason |
|---|---|---|
zone.push("frame") |
yes | |
zone.pop() |
yes | the popped name is discarded |
local name = zone.pop() |
no | the popped name is kept |
holder.zone.push("frame") |
no | the receiver is not a bare name |
other.push("frame") |
no | other is not nupp.profile.zone |
Place zone boundaries around phases, outside inner loops. The other forms above make ordinary function calls, as do enter and leave. bench.keep has similar inlining rules; see Benchmarks for the matching sink rule.
enter and leave#
Use zone.enter and zone.leave when a zone might outlive the profiling session, such as in a coroutine resumed after profiling stops. enter returns a token. If the session has ended, leave ignores that token, so it cannot pop a zone from a later session:
Trace aborts#
nupp run --jit-aborts app.nuppThe command writes jit-aborts.csv:
severity,count,reason,location,zone,rootLocation
warn,7,NYI: bytecode FNEW,library.nupp:41,frame/spawn,app.nupp:20
Each row gives the root trace's starting location, the location where recording stopped (including runtime libraries), its count, and the active zone. Rows are ordered by severity:
blacklist: LuaJIT has stopped retrying this trace for the rest of the process. Prioritize these when they affect hot code.warn: a failed compilation attempt. Use sampling to see how much time the affected code takes.info: normal trace events, such as leaving a loop or encountering recursion. Included byrun --jit-aborts;profile.trace()omits them unlessincludeBenign = trueis requested.
NYI: bytecode FNEW means LuaJIT encountered function construction while recording a trace. If the function is created inside a loop, move its declaration outside the loop and pass changing values as arguments. Run again to check for other blockers. See LuaJIT trace checking for the reason catalog and examples.
Structured output#
nupp run --jit-aborts=jit-aborts.json --json app.nuppEach entry includes the raw VM details, a stable reasonId, and a class. rootLocation identifies the original trace across calls and side traces. The report also identifies the trace profile and reason catalog used. Compilation of lazily loaded modules is excluded from both CLI profiling sessions.
Profiling a benchmark#
nupp bench --profile writes one collapsed-stack file per benchmark:
nupp bench --case '^floats$' --profile build/bench-profiles# Profile: build/bench-profiles/001-sum.floats.ipairs:size=100.collapsedSampling happens in a separate pass after timing, so profiling overhead does not affect the measured result. Only the run callbacks are sampled; setup, teardown, and benchmark harness code are excluded. --profile-interval-ms changes the one-millisecond interval and --profile-zone keeps one zone subtree.
When using multiple forks, only the first is profiled.
If a benchmark slows down and its profile shows _[I], check for trace aborts:
nupp run -O1 --jit-aborts bench/sum.bench.nupp --case 'sum.floats.index:size=100'nupp bench also records abort sites. A new abort seen in every fork fails a comparison against a baseline. See Benchmarks.
Profiling from a program#
Use nupp.profile directly to capture part of a run, such as one frame, one request, or the work after warm-up:
local profile = nupp.profile

with session = profile.sample({intervalMs = 2, zone = "frame/render"}) do
    renderEverything()
    local report = session:stop("render.out")

    print(report.samples, report.stacks)
end
stop ends the session and returns a report. tostring(report) gives the same text written to the file. Use pause and resume to exclude work without ending the session; nupp bench uses them to exclude setup and teardown.
The zone option filters the report when you call stop, adding no filtering overhead during sampling. All zones are sampled, but the filter is fixed when the session starts and cannot be widened afterwards.
Collecting aborts#
Use profile.trace() to collect trace aborts:
with session = profile.trace() do
    runTheWorkload()
    local report = session:stop()

    if report.blacklisted > 0 then
        print(tostring(report))
    end
end
Session lifecycle and cost#
Profiling hooks apply to the whole process. One sampling session and one trace session can run at a time; starting a second session of either kind is an error. A session is a nupp.Closeable, so a with ends it where the block ends: a session nothing stopped is closed without a report, and closing one that stop already ended does nothing.
Each sample requires a timer interrupt, a stack walk, and a table write. Trace profiling runs a callback on each abort. Keep captures short to limit overhead.
Native GPU costs#
Use a caller-named JSONL file to collect native GPU costs:
nupp run --gpu-costs frame-costs.jsonl src/main.nupp
nupp bench --gpu-costs build/gpu-costs
run selects one file. bench creates a unique run directory with separate files for each case, variant, fork, and comparison executable. Native hosts can set NUPP_GPU_COSTS to a unique path before starting the process. The runtime helper nupp.runtime.provider.nativegpu.costsOutput(path) selects an output; passing nil restores the environment default, which is truncated only the first time the process opens it and appended to when restored. sequence runs on across every output a process writes. A failed write never fails the GPU work it describes: the next call that can fail cleanly reports it, and costsOutput reports it while still switching to the new output.
Each line is a JSON object with schemaVersion: 1, processId, sequence, context, target: "gpu", and operation. Records distinguish adapter/device setup, pipeline creation, buffer allocation, upload, dispatch, synchronization, readback, host copies, and cleanup. hostMs measures elapsed host API time. adapterDevice splits that setup into adapterMs and deviceMs; pipeline records carry phase: "setup", and dispatches distinguish first-use from steady-state.
When the adapter supports timestamp queries, kernelExecution.gpuMs measures the compute pass on the device. Join it to dispatch by context and dispatch. Queries are resolved at synchronization after the measured work completes, preserving asynchronous dispatch and attributing counters to the current work. Unsupported adapters report gpuTiming: "unavailable" and gpuMs: null; equal or reversed device counters do the same, with gpuTimingReason explaining the invalid interval. Records retain gpuTicksBegin and gpuTicksEnd as decimal strings and gpuTickPeriodNs without losing integer precision. Host submission time is never substituted for device time. Timestamp readback reports its own instrumentationHostMs. Collection adds query resources and JSON output work, so compare variants with the same instrumentation settings. Host and GPU times can overlap and must not simply be summed.
A dispatch includes authored kernel metadata (sourceFile, sourceLine, artifactId, parameter names), work-item and workgroup dimensions, binding reuse, and read/write buffer versions. kernelIdentity and bindBuffer records also connect kernel storage slots to buffer handles. This join identifies an upload that occurred before its first binding. Buffer layout metadata retains format, element width, shape, strides, offset, and count. Typed spans preserve their bytes without format conversion, recorded explicitly as conversion.
Uploads advance a buffer version; each dispatch advances every writable buffer once. Downloads retain the version captured when their copy was queued, even if a later upload or dispatch changes the resident buffer before readback. downloadQueue reports byte count and fresh staging allocation; downloadMapCopy reports the staging-to-host copy, and downloadHostCopy the copy into the caller's span. These records expose the existing two-copy path and synchronization costs before any residency optimization is attempted.